AI 编码 Agent 省 2.7x Token 的本地索引
XERJ 是本地 AI 搜索引擎,自动索引文件夹让编码 Agent 直接拉取所需代码而非逐文件读取。实测让 Agent 输出 token 减少 2.7 倍且保持同等解题率,日常场景可达 5 倍节省。
XERJ is the new way for AI to search data. Its autoindex capability activates agents to know your data without the token waste of grep and sed. One command indexes code, docs, logs and PDFs for search, RAG, security audits and agent memory, using 40x fewer tokens than grep. Elasticsearch compatible, so existing clients just work.
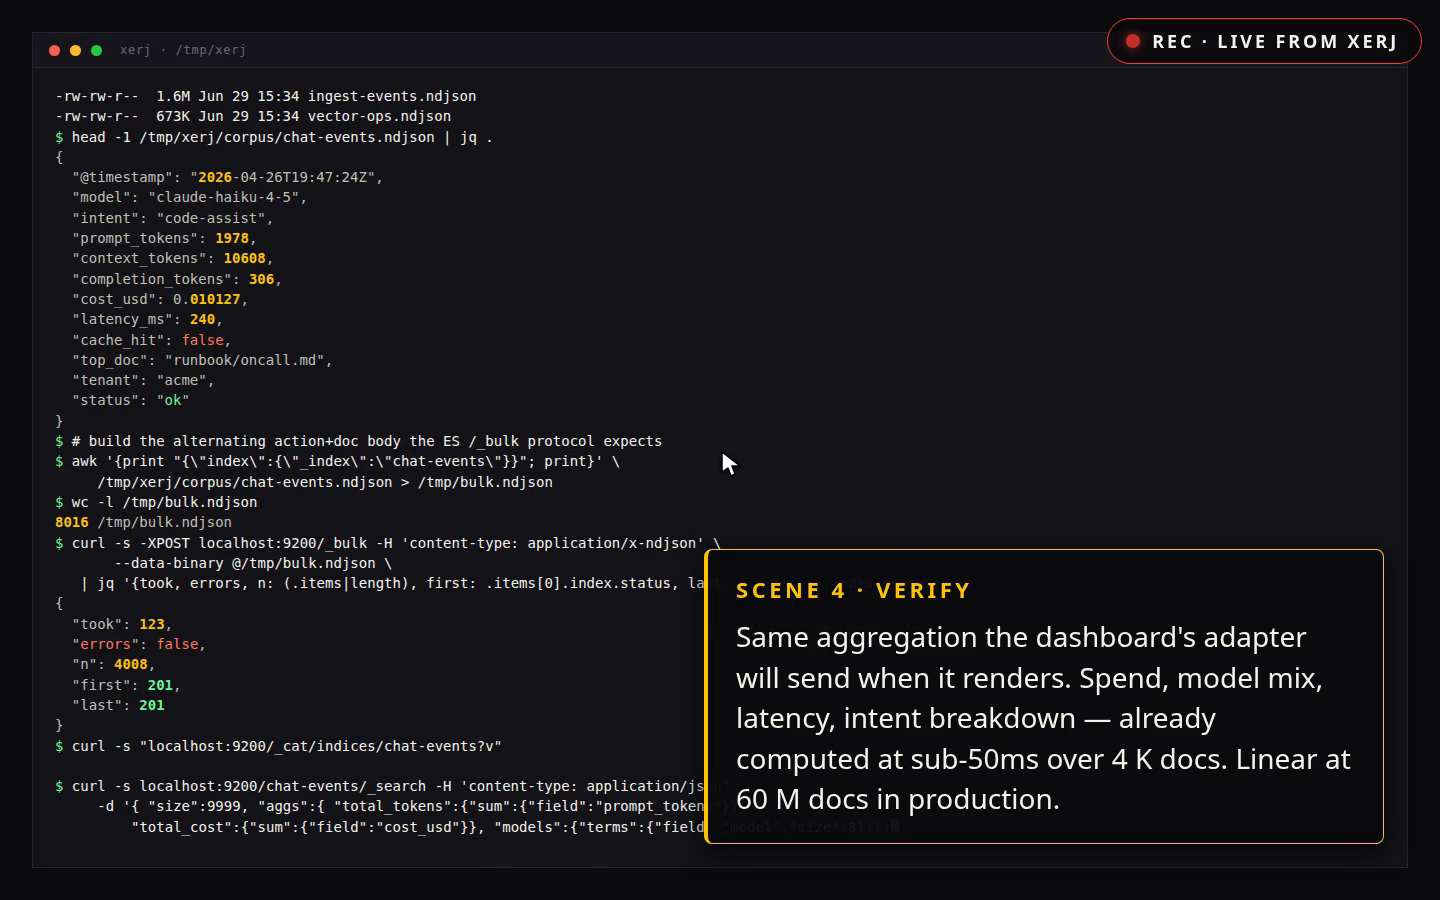
编码 Agent 的上下文成本是目前最隐蔽的规模化瓶颈,Cursor、Windsurf 这类工具靠云端索引解决,但企业私有代码库走不通。XERJ 的差异化在于完全本地运行 + 自动索引任意文件夹,对标方案如 Sourcegraph Cody 或 Continue.dev 需要手动配置 repo 且依赖云端 RAG。
真正值得关注的场景是 CI/CD 和自动化 Agent:当 Agent 需要批量处理陌生代码库时,逐文件读取的 token 消耗会指数级爆炸。XERJ 的 reference coding 模式让 Agent 先"偷看"同类开源项目的解法再动手,这个思路比单纯压缩上下文更根本。
如果你在构建内部编码 Agent 或做 Devin 类产品的基础设施,建议对比测试它的索引召回率 vs 纯向量方案,尤其是跨语言调用链的场景。
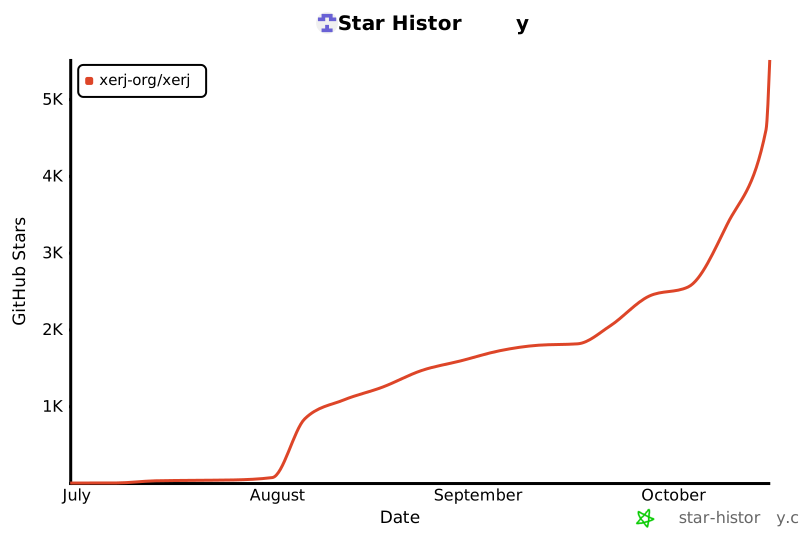
面向AI Agent的本地语义搜索引擎,以自动索引和Token优化替代传统grep检索
独特价值:Elasticsearch兼容的Agent原生搜索,索引即服务,Token消耗降低40倍